From an idea, an edition.
An editorial studio on your computer: research, writing, illustration, layout, narration and video in one pipeline, built around local models.
One idea, eight formats.
Everything below came out of the app, on our own computer, on the night of October 25, 2026.
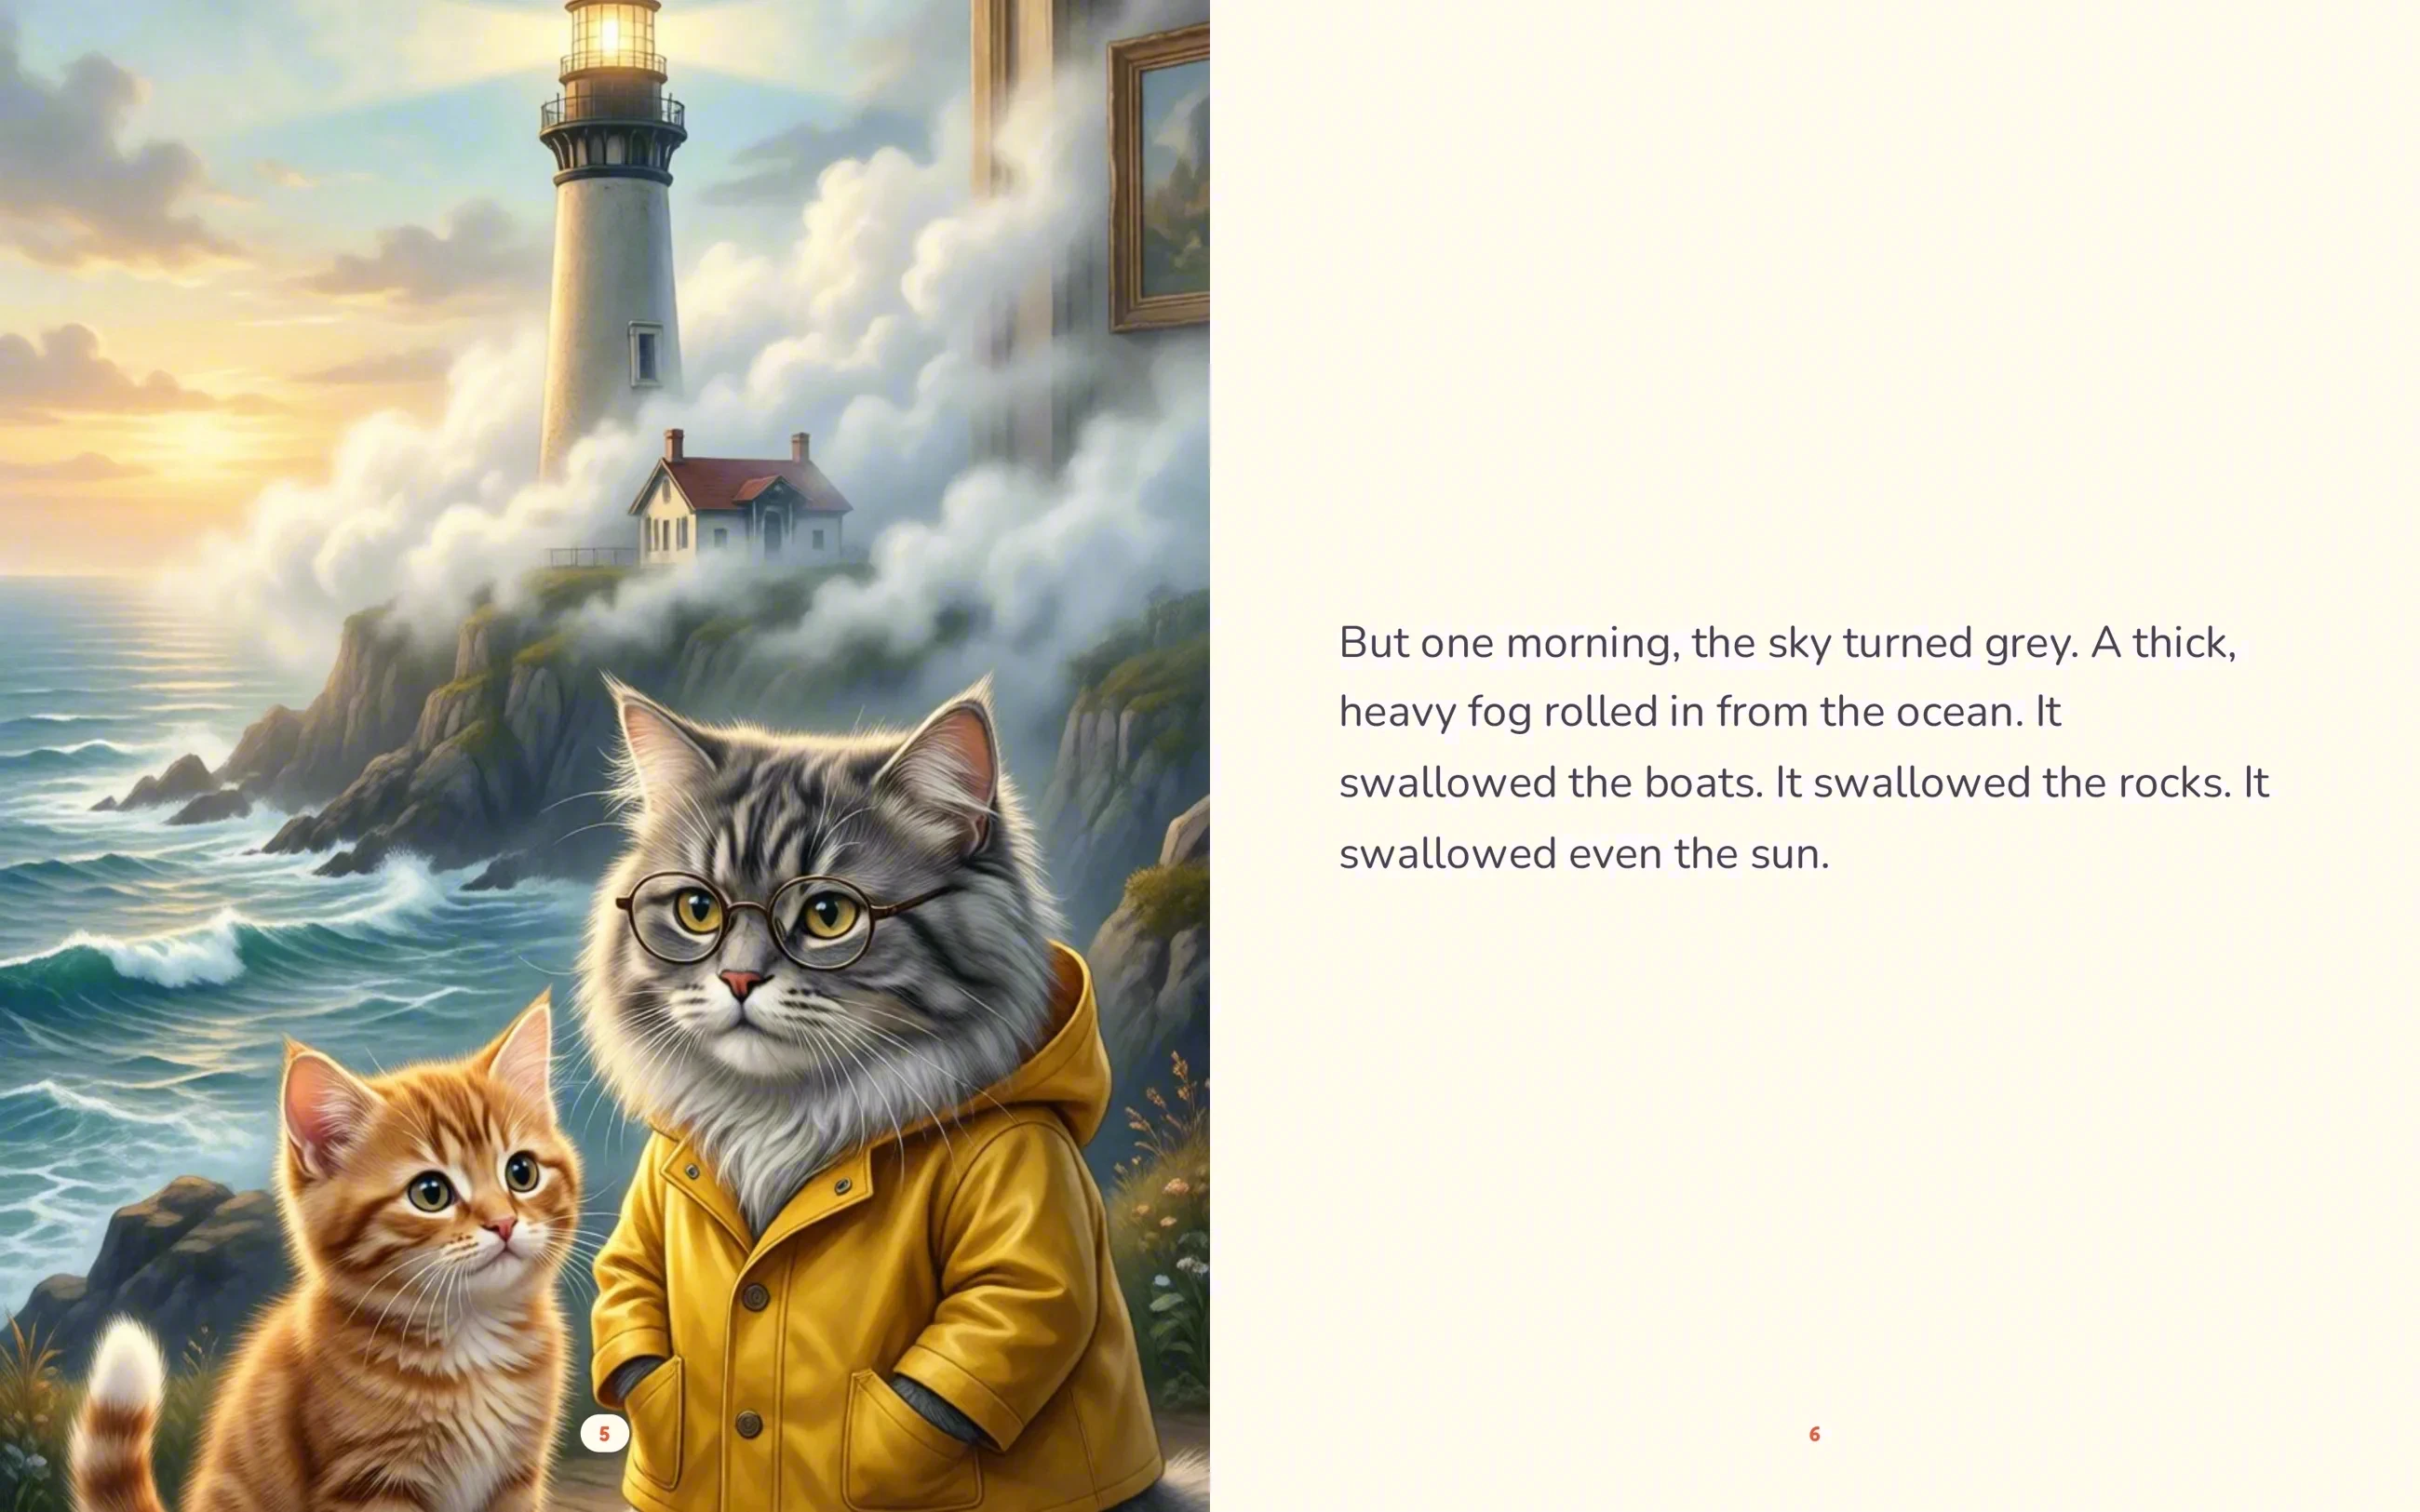
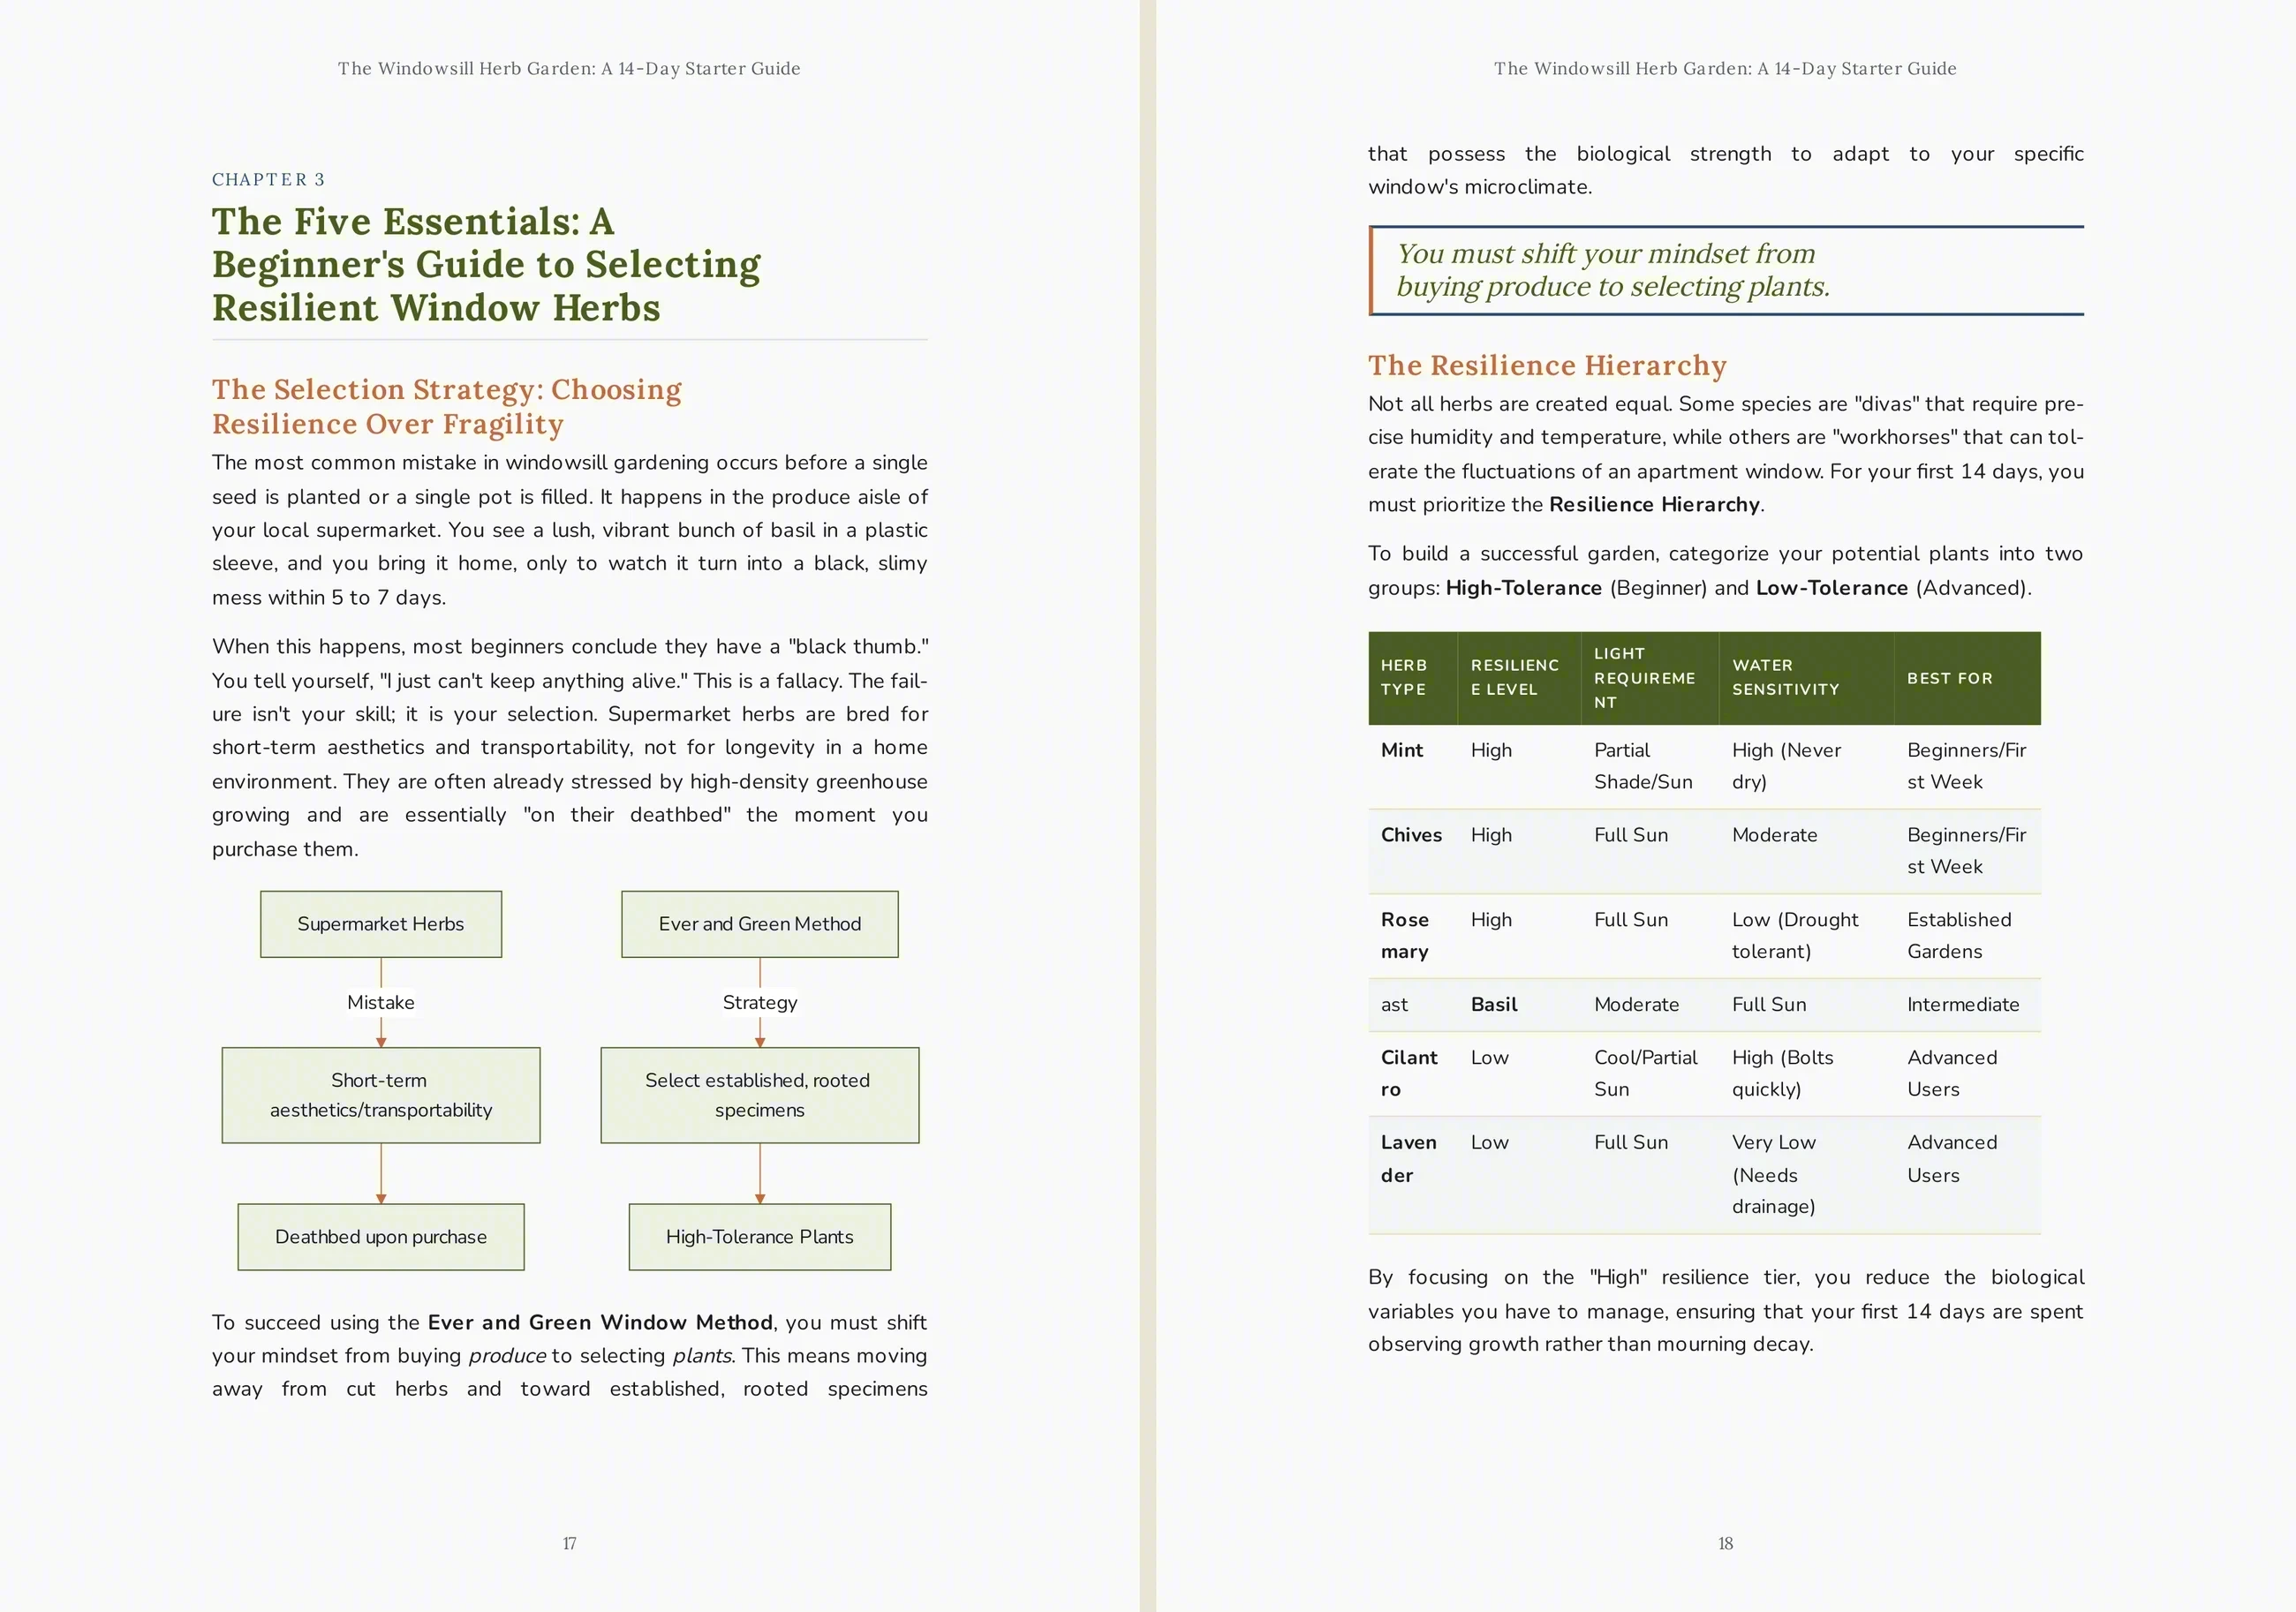
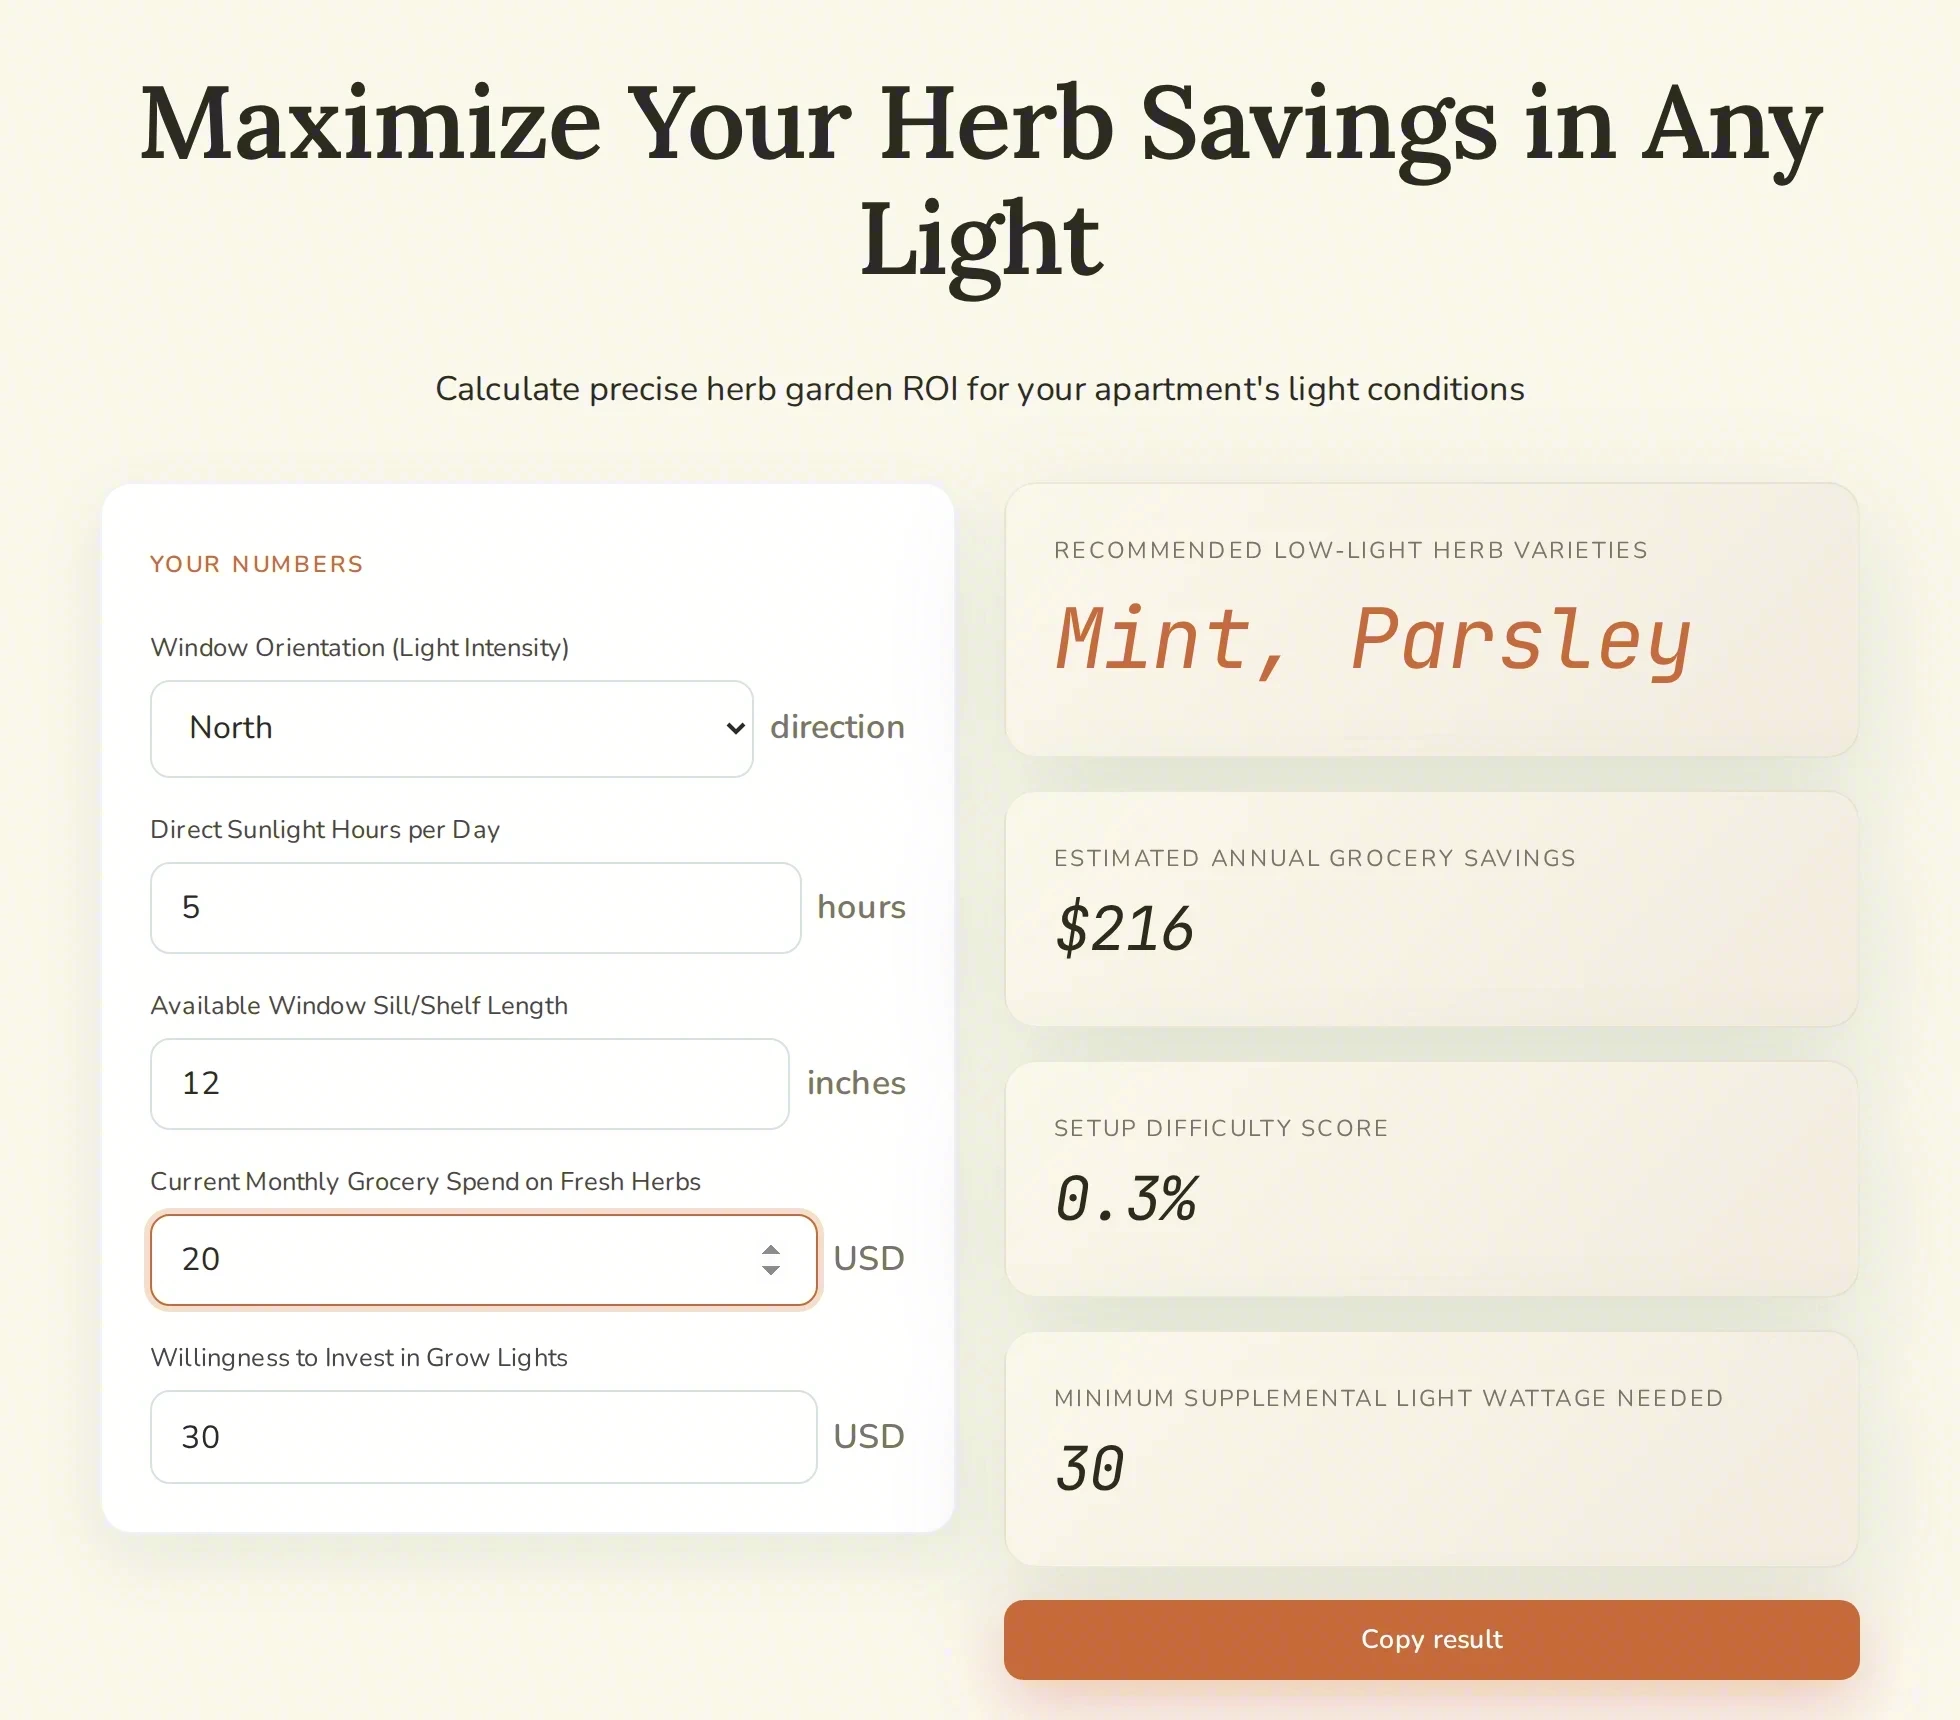
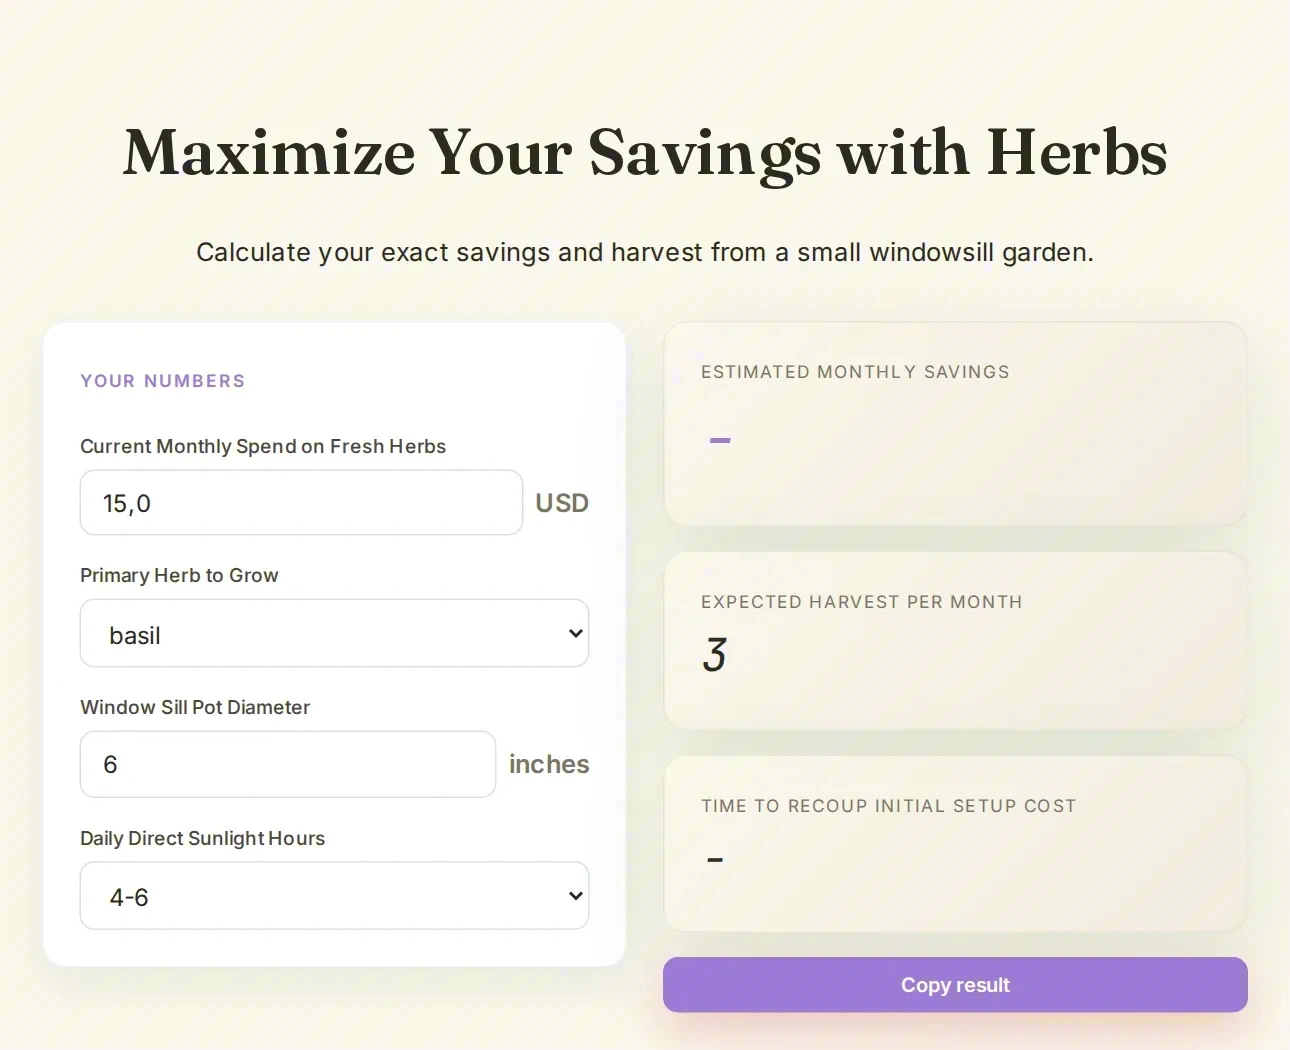
Turn the pages. Press play.
Live samples, the same files a buyer receives. All made locally on one machine (RTX 4000 Ada 20 GB + 125 GB RAM) with Apache-2.0 models.
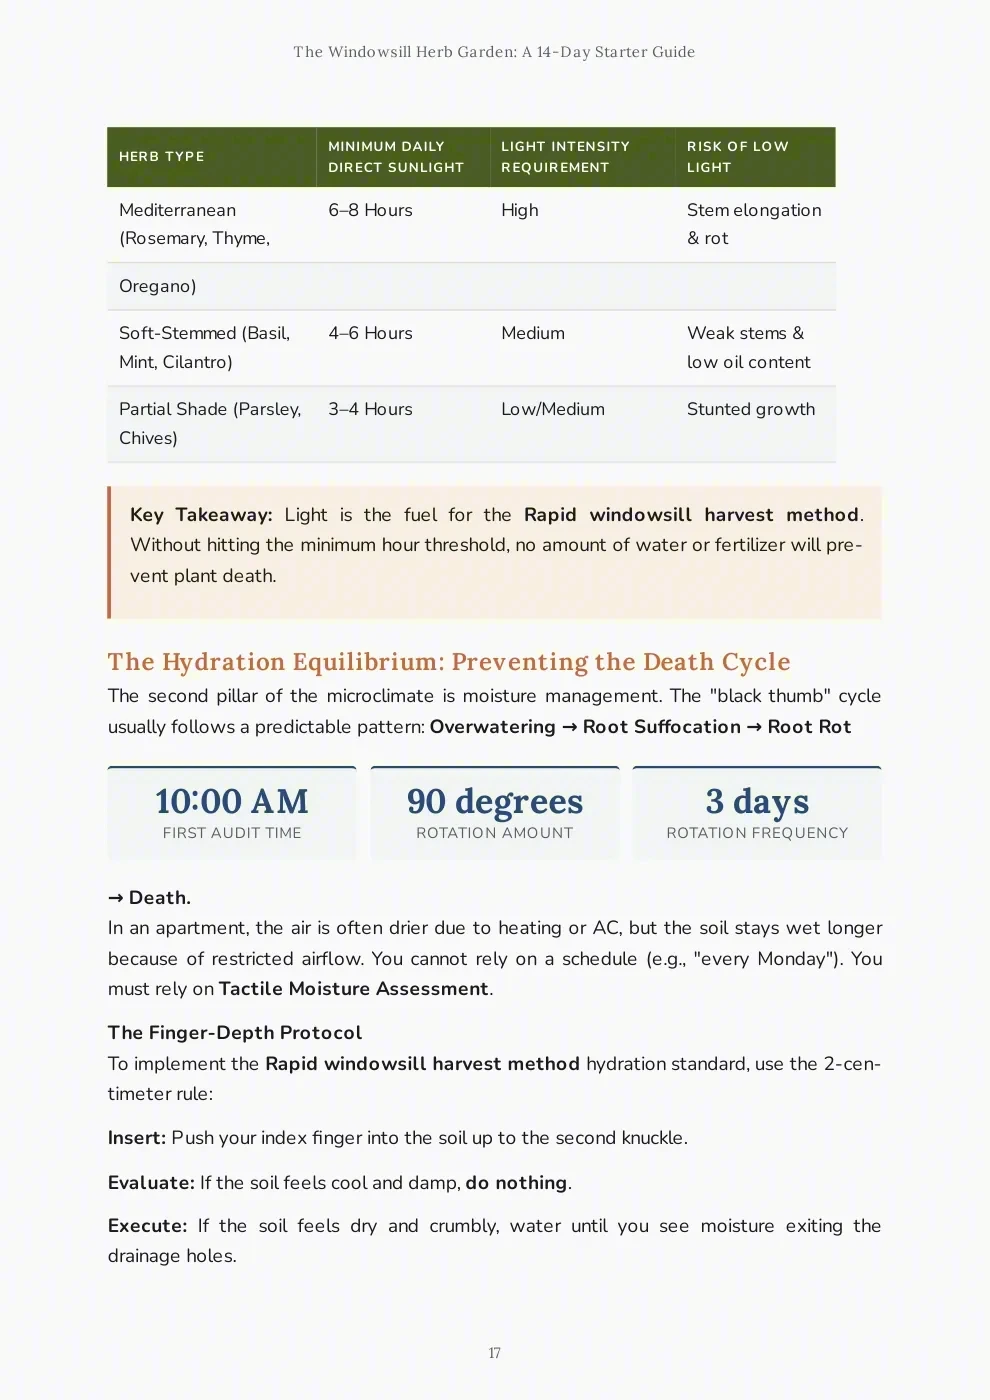
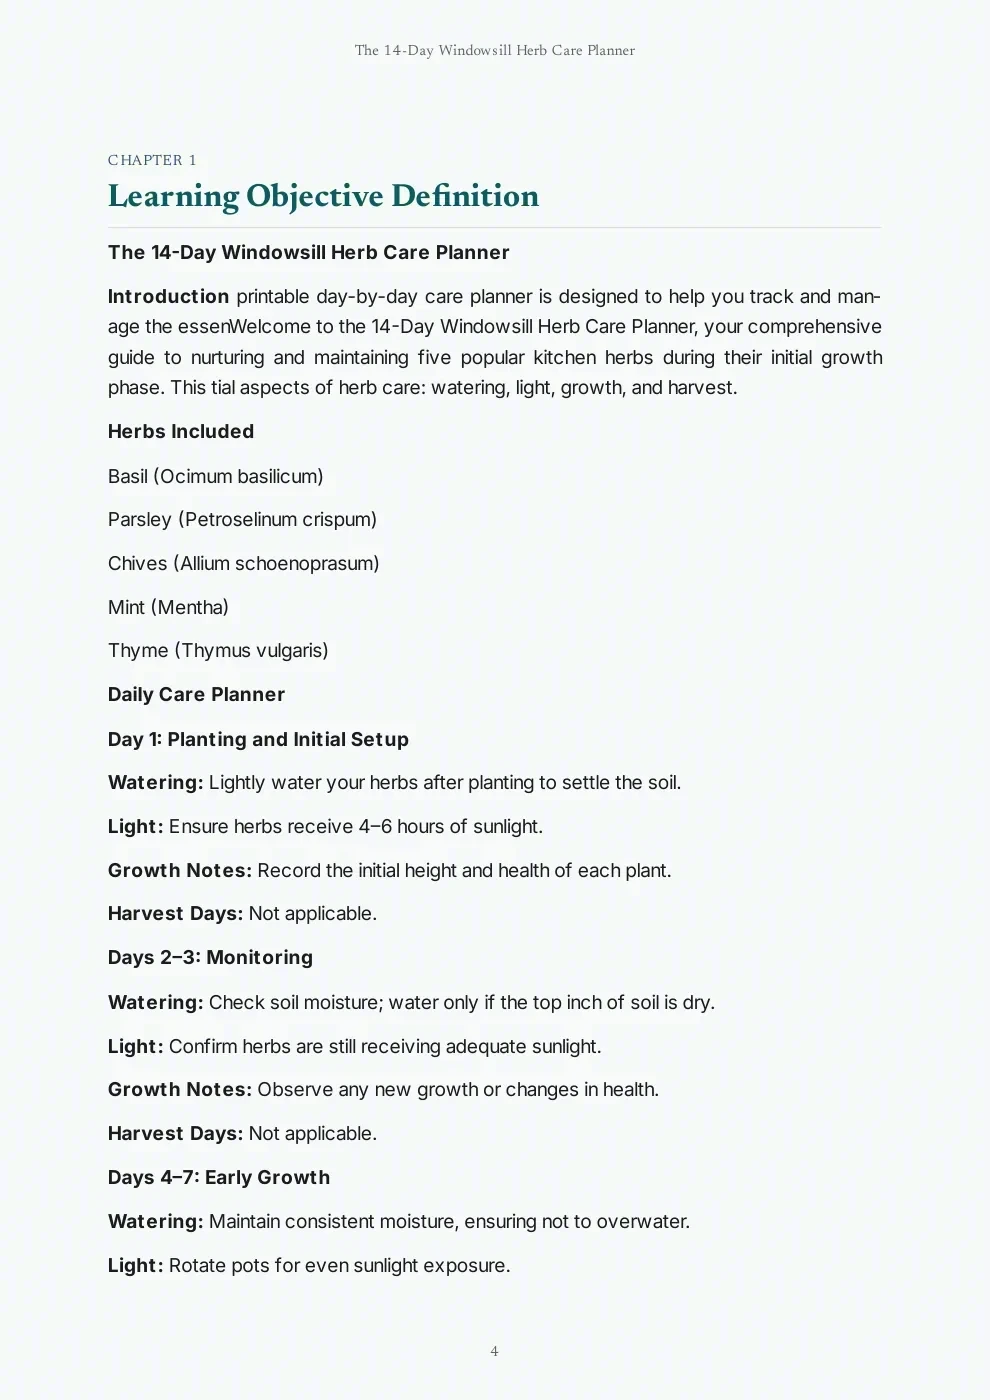
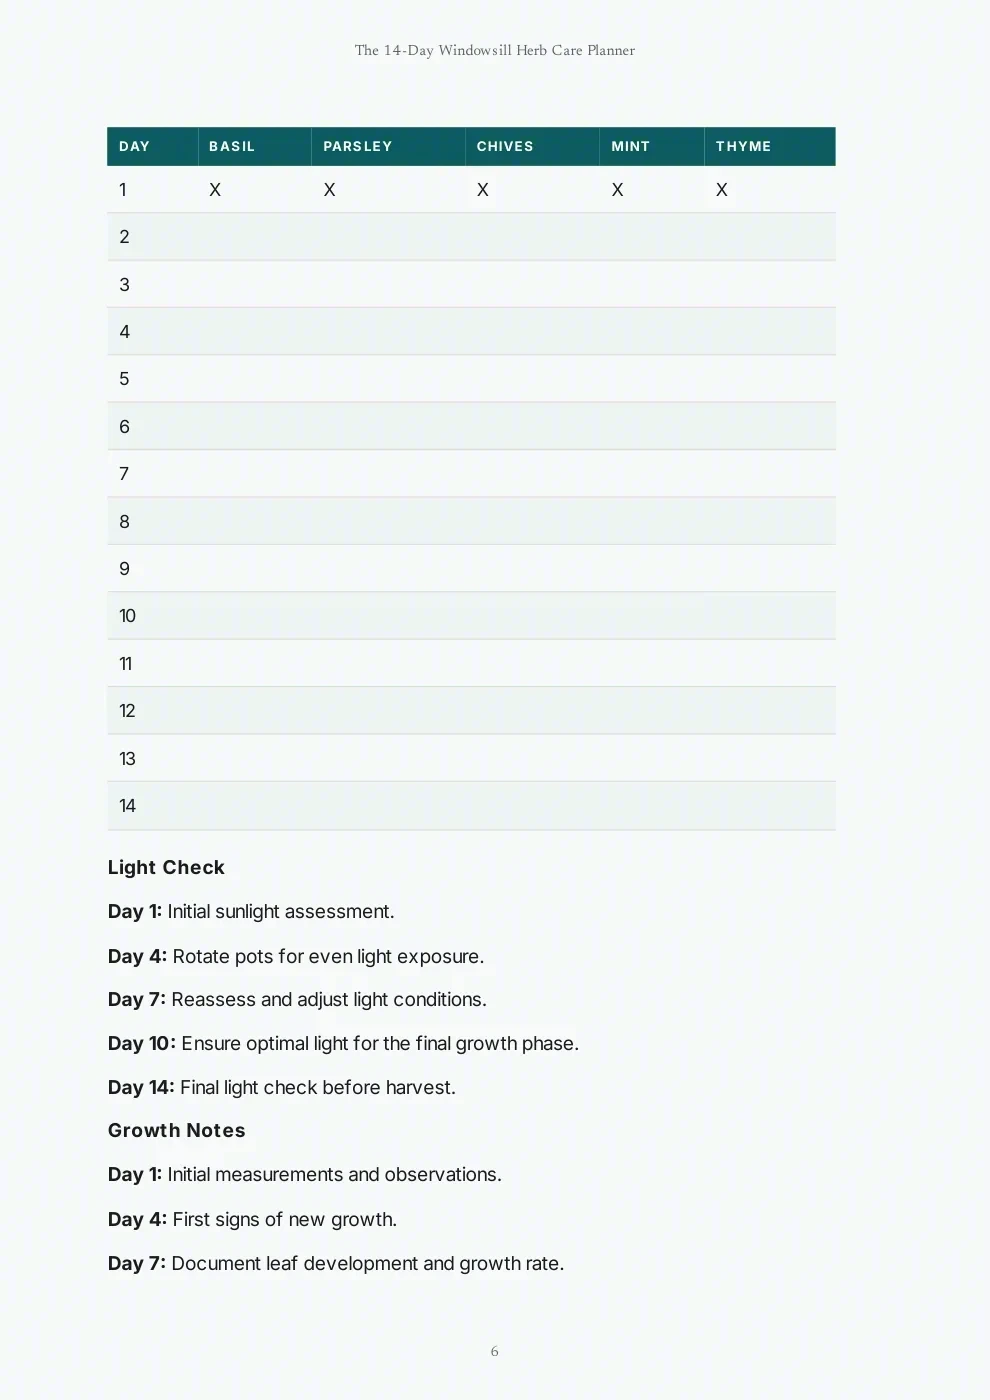
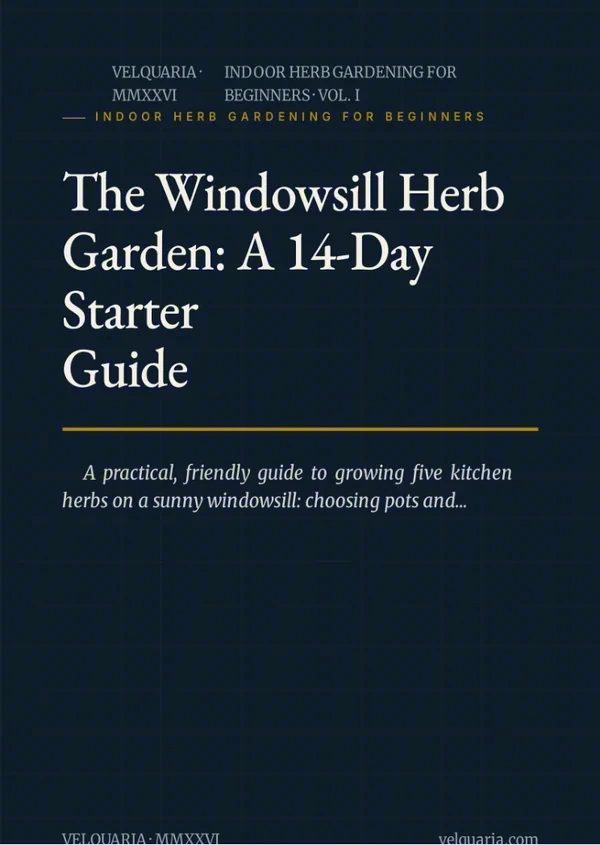
The Windowsill Herb Garden
14-Day Herb Care Planner
Herb Garden Setup Checklist
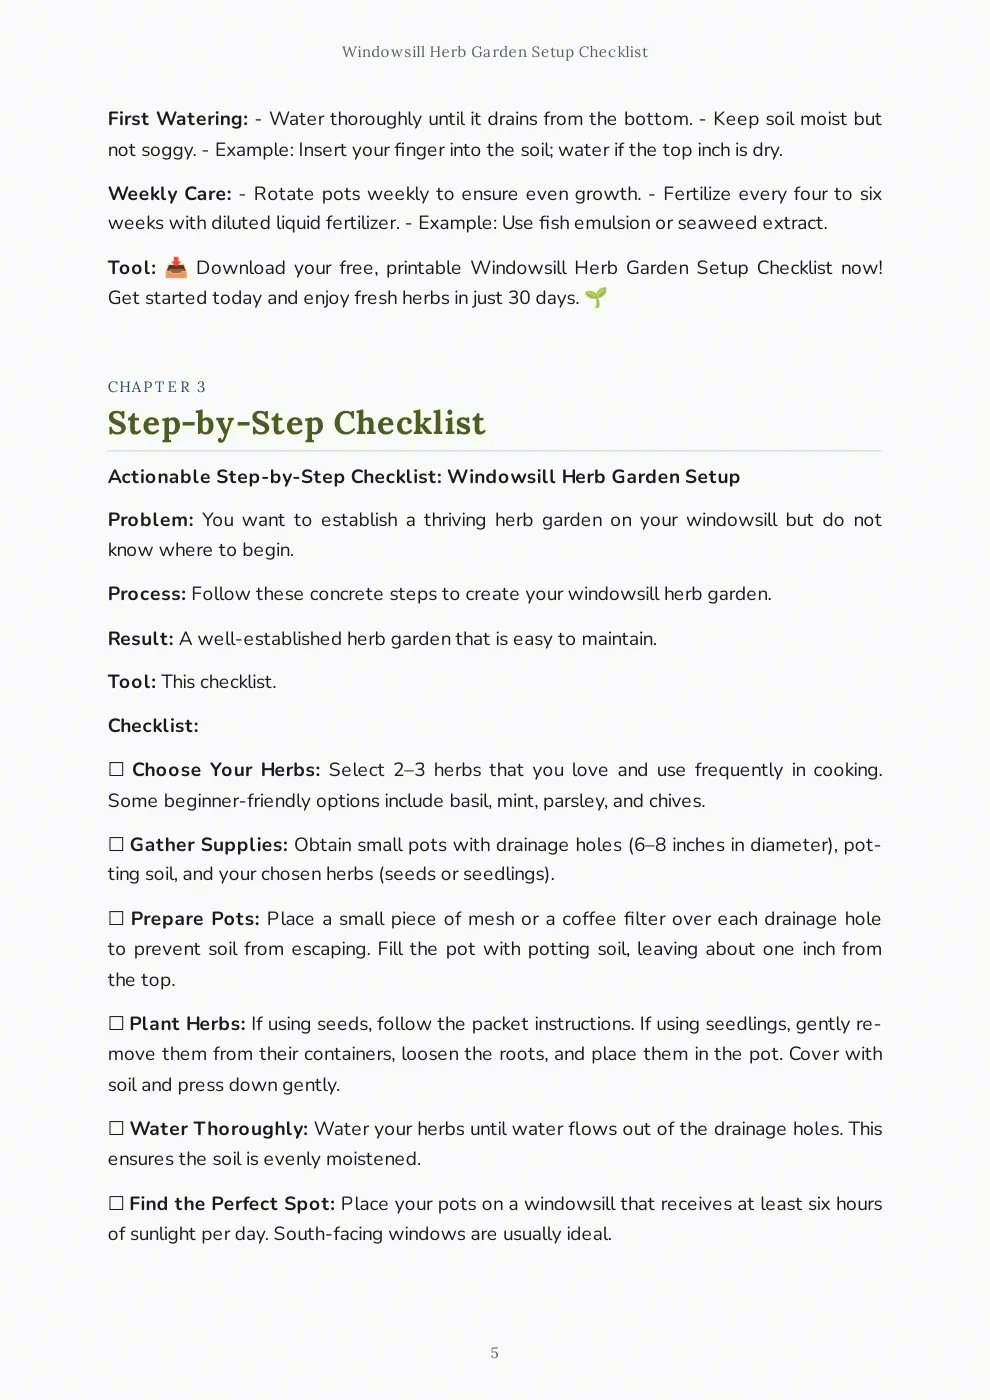
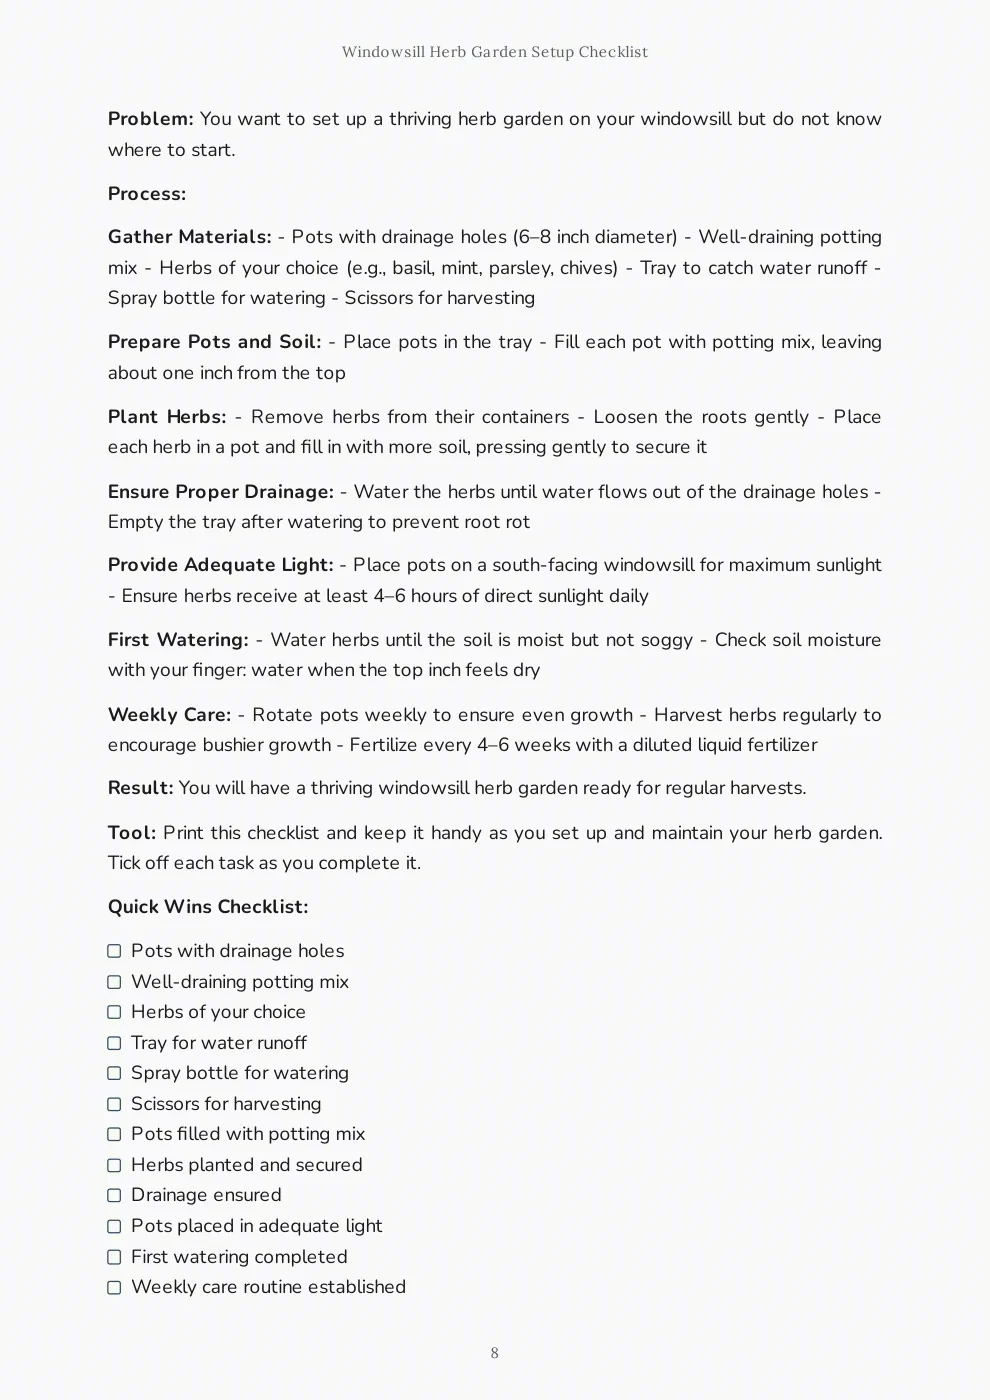
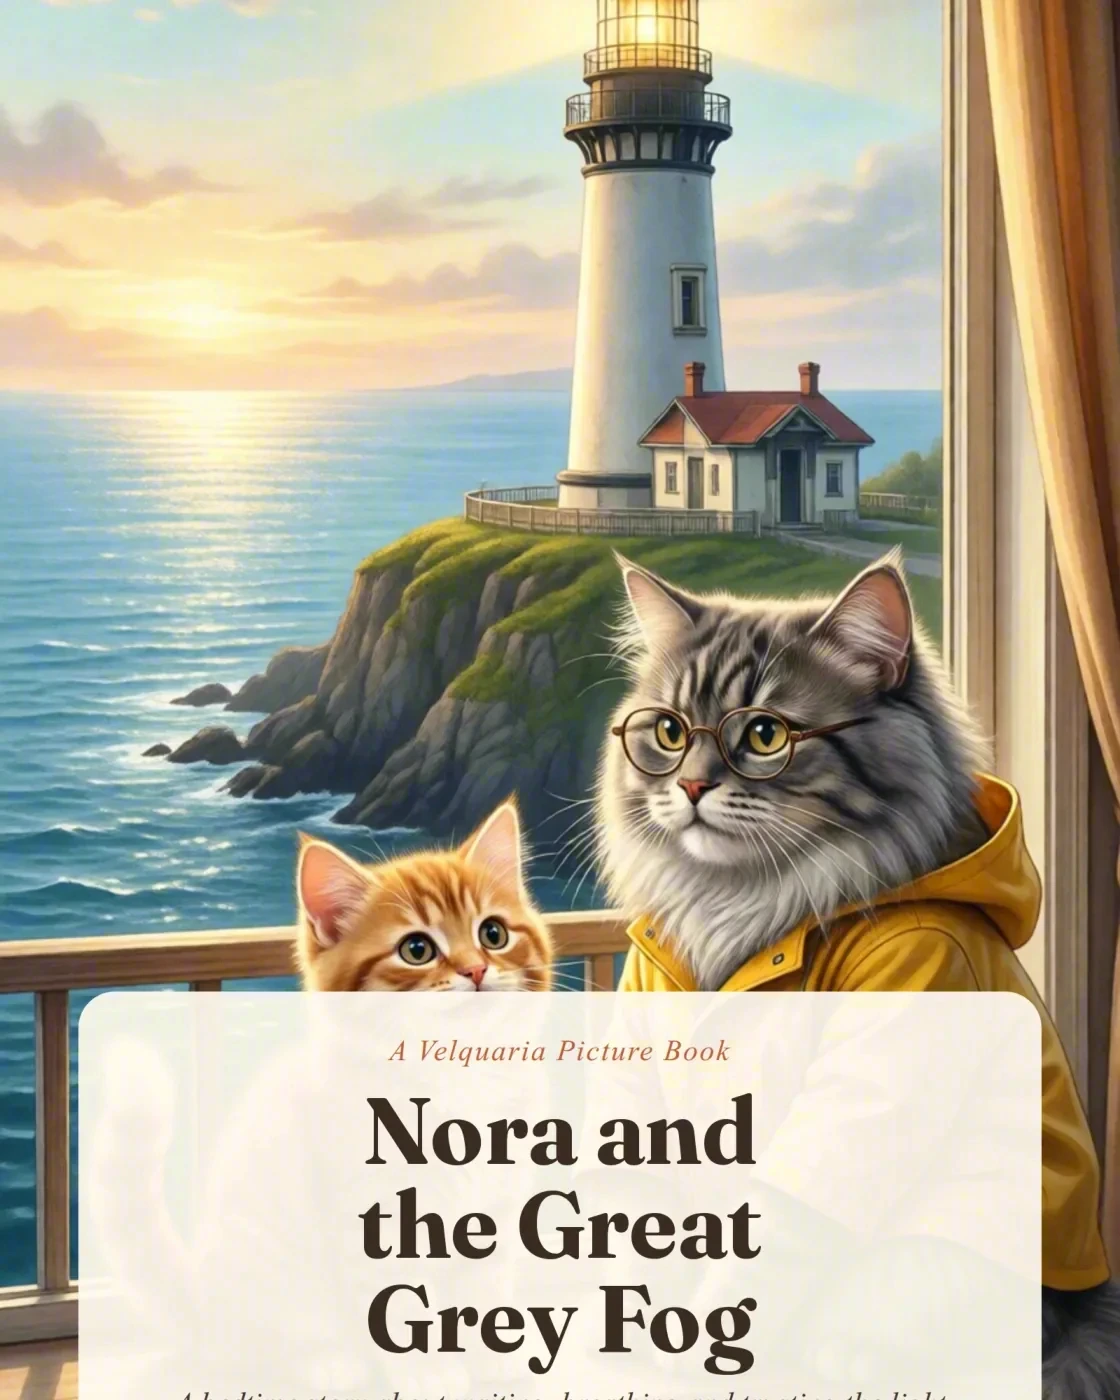
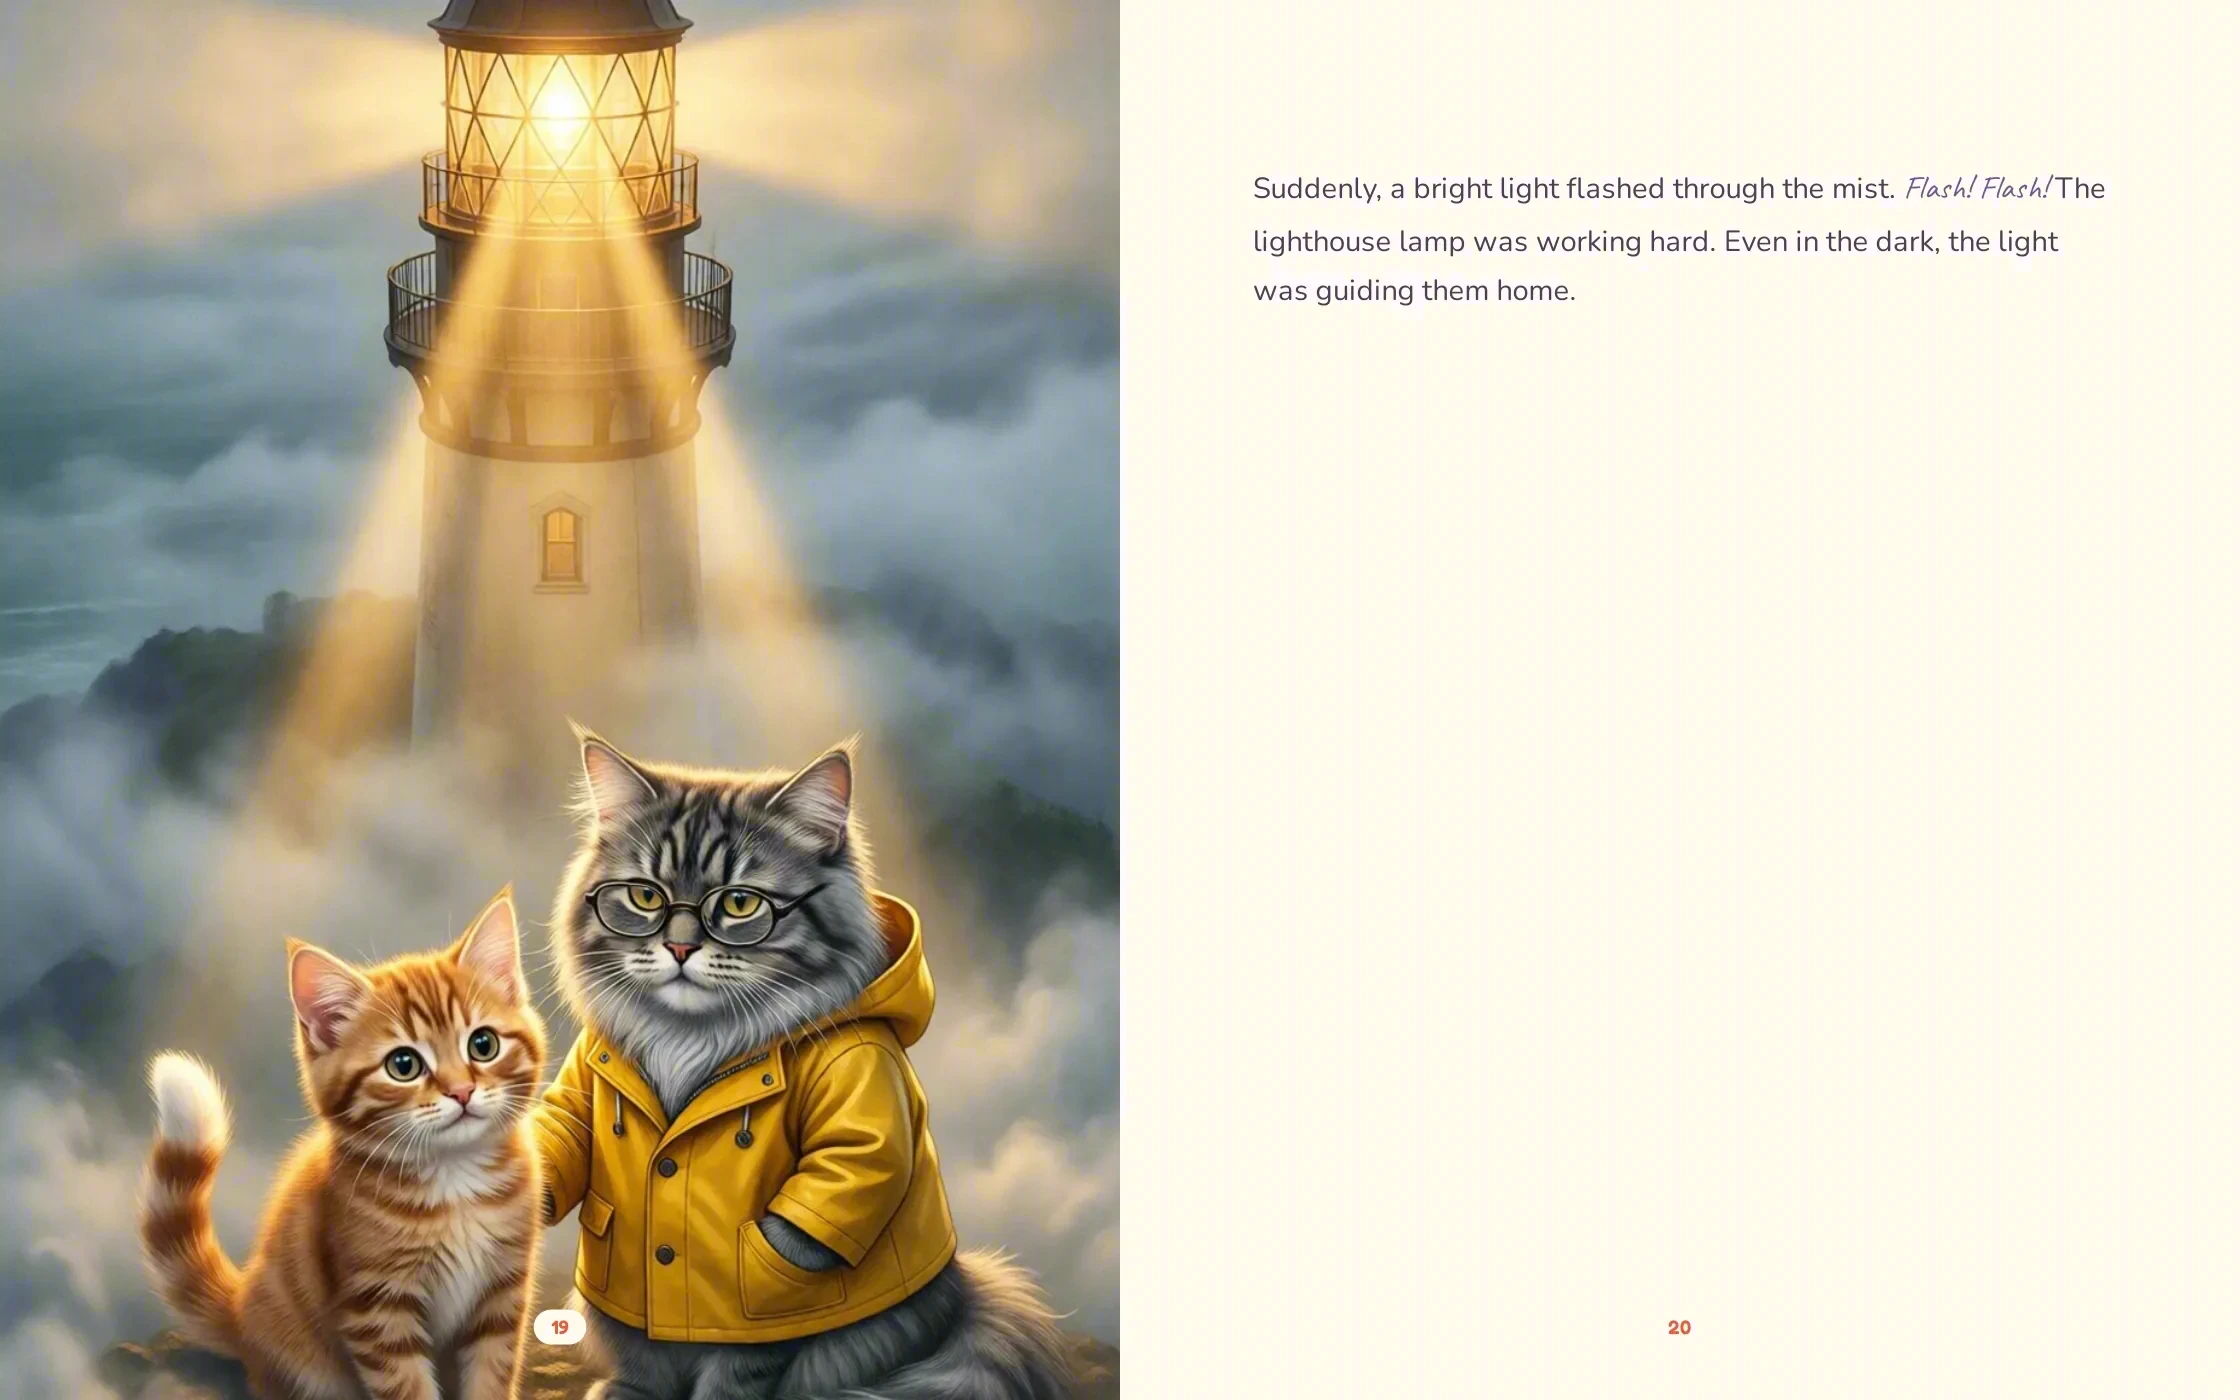
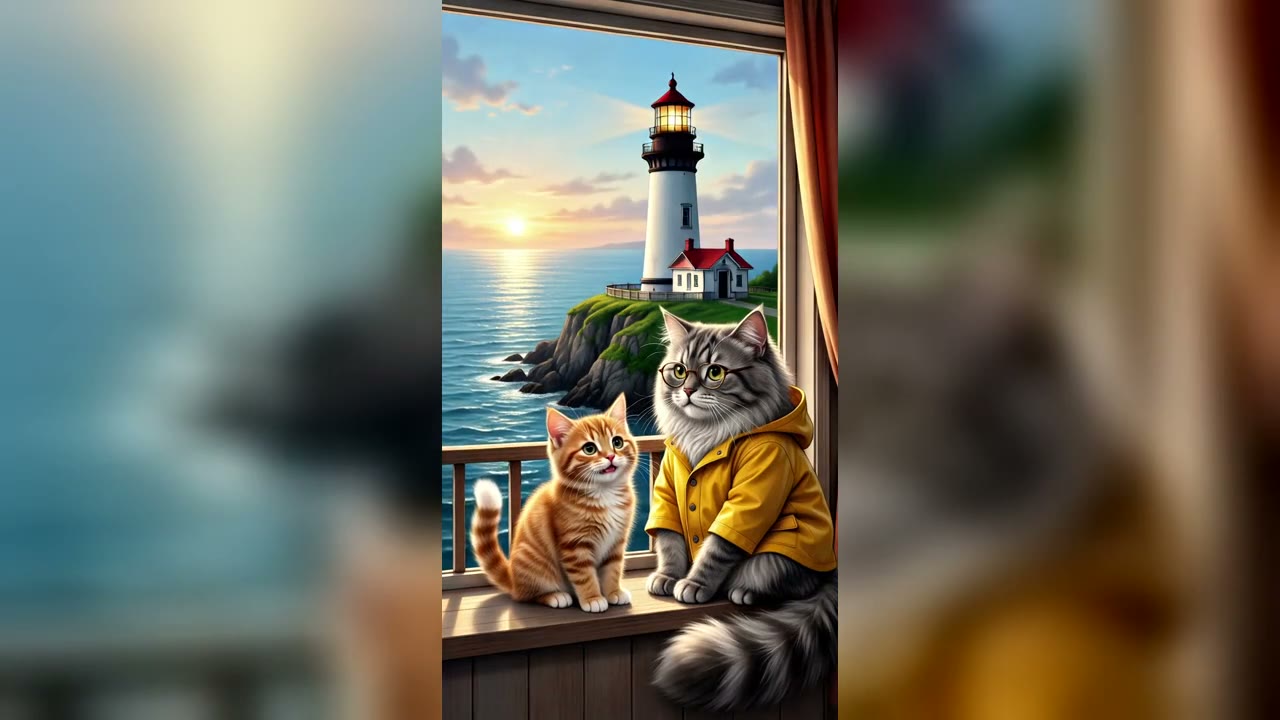
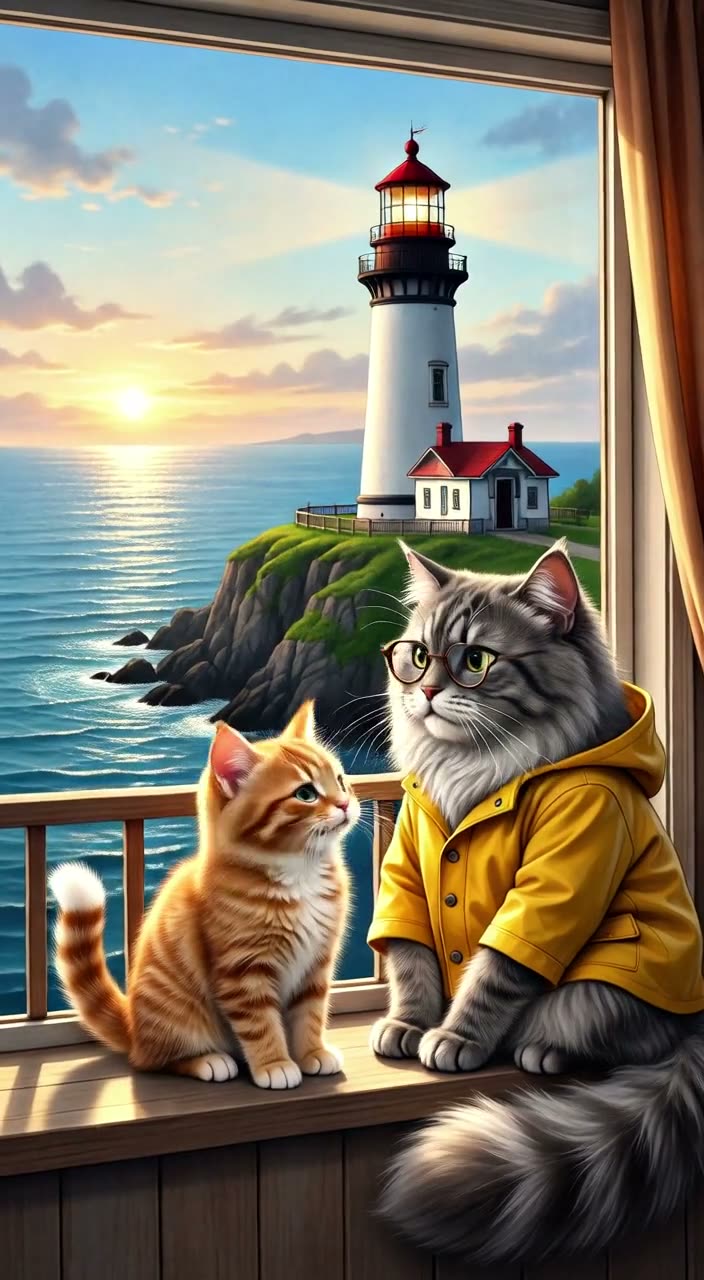
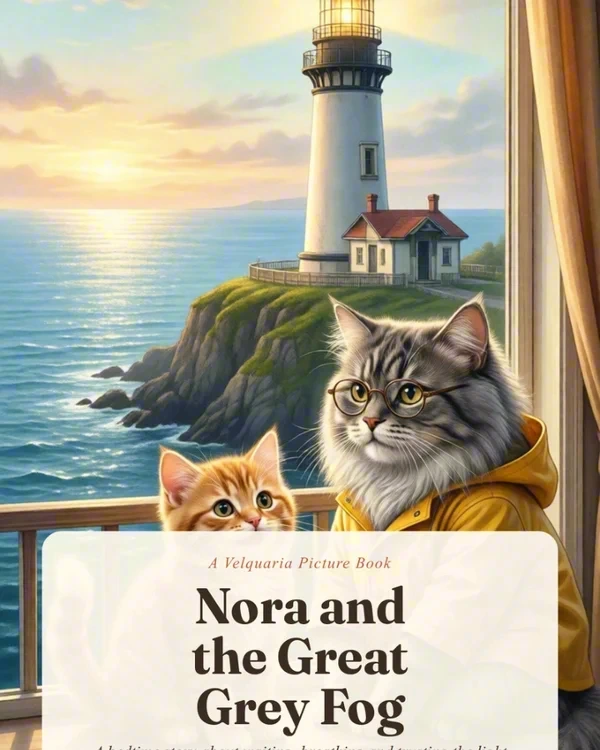
Nora and the Great Grey Fog
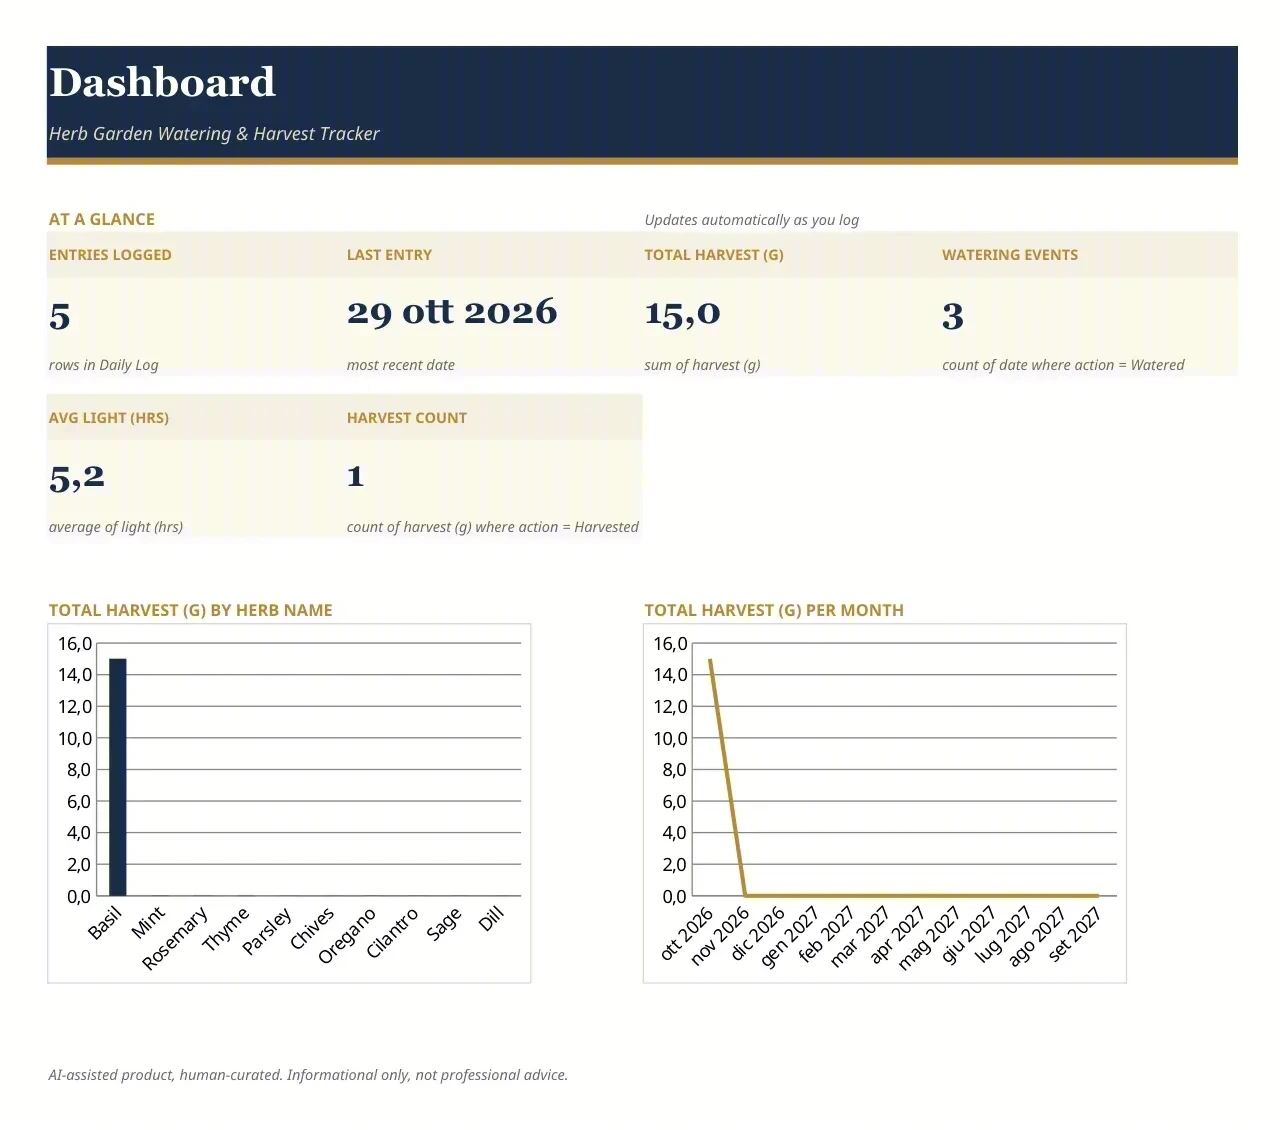
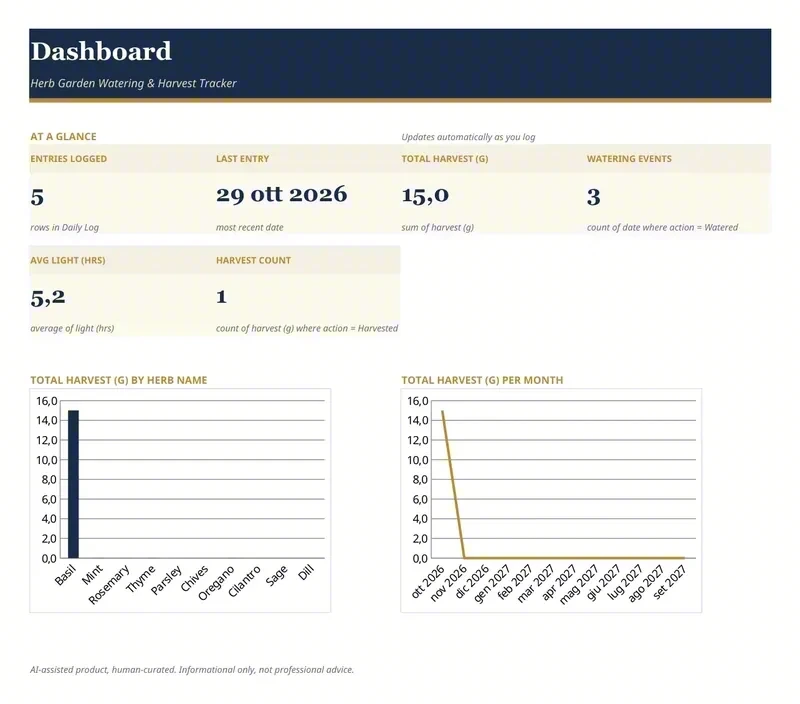 Dashboard
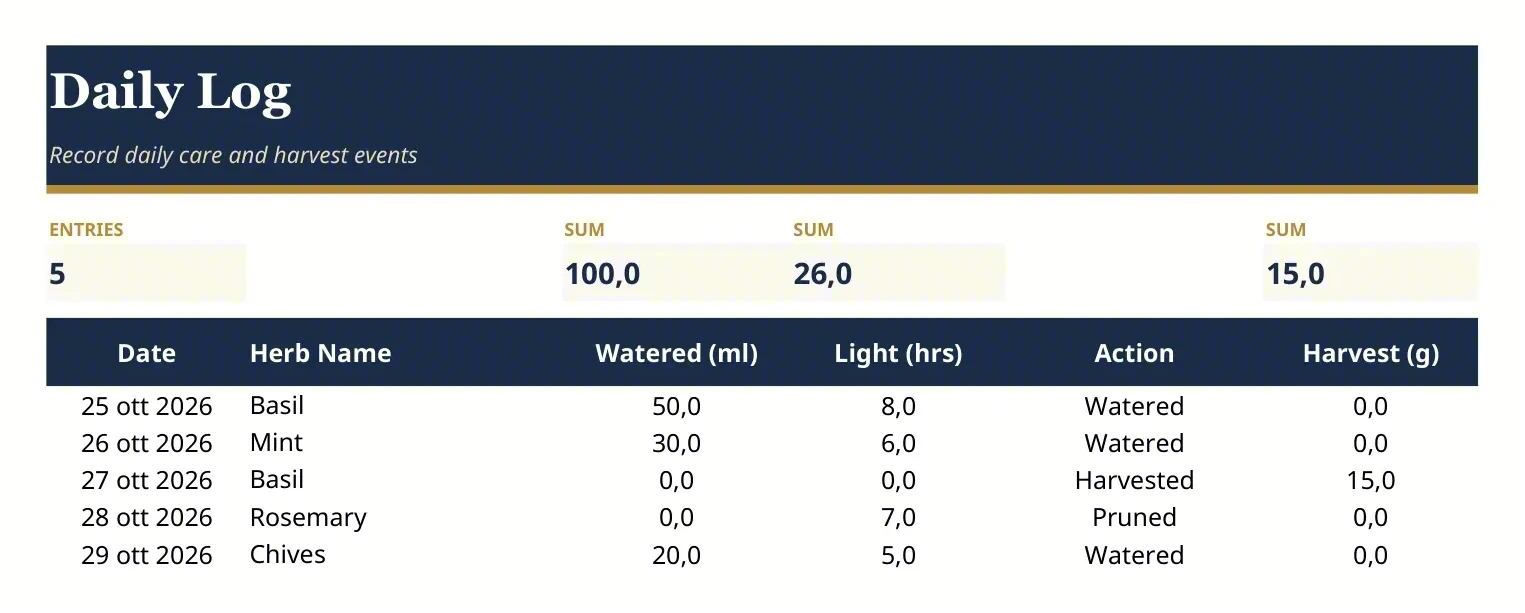
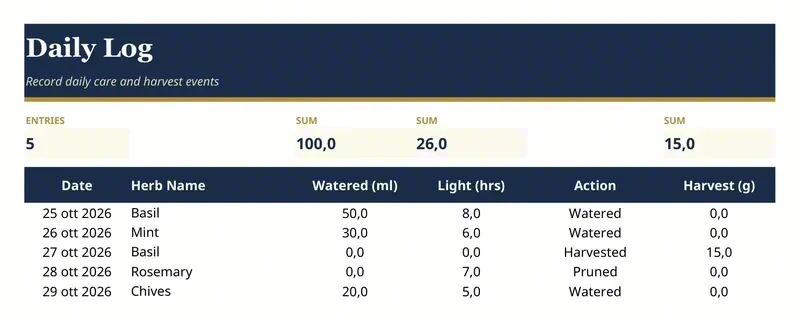 Daily Log
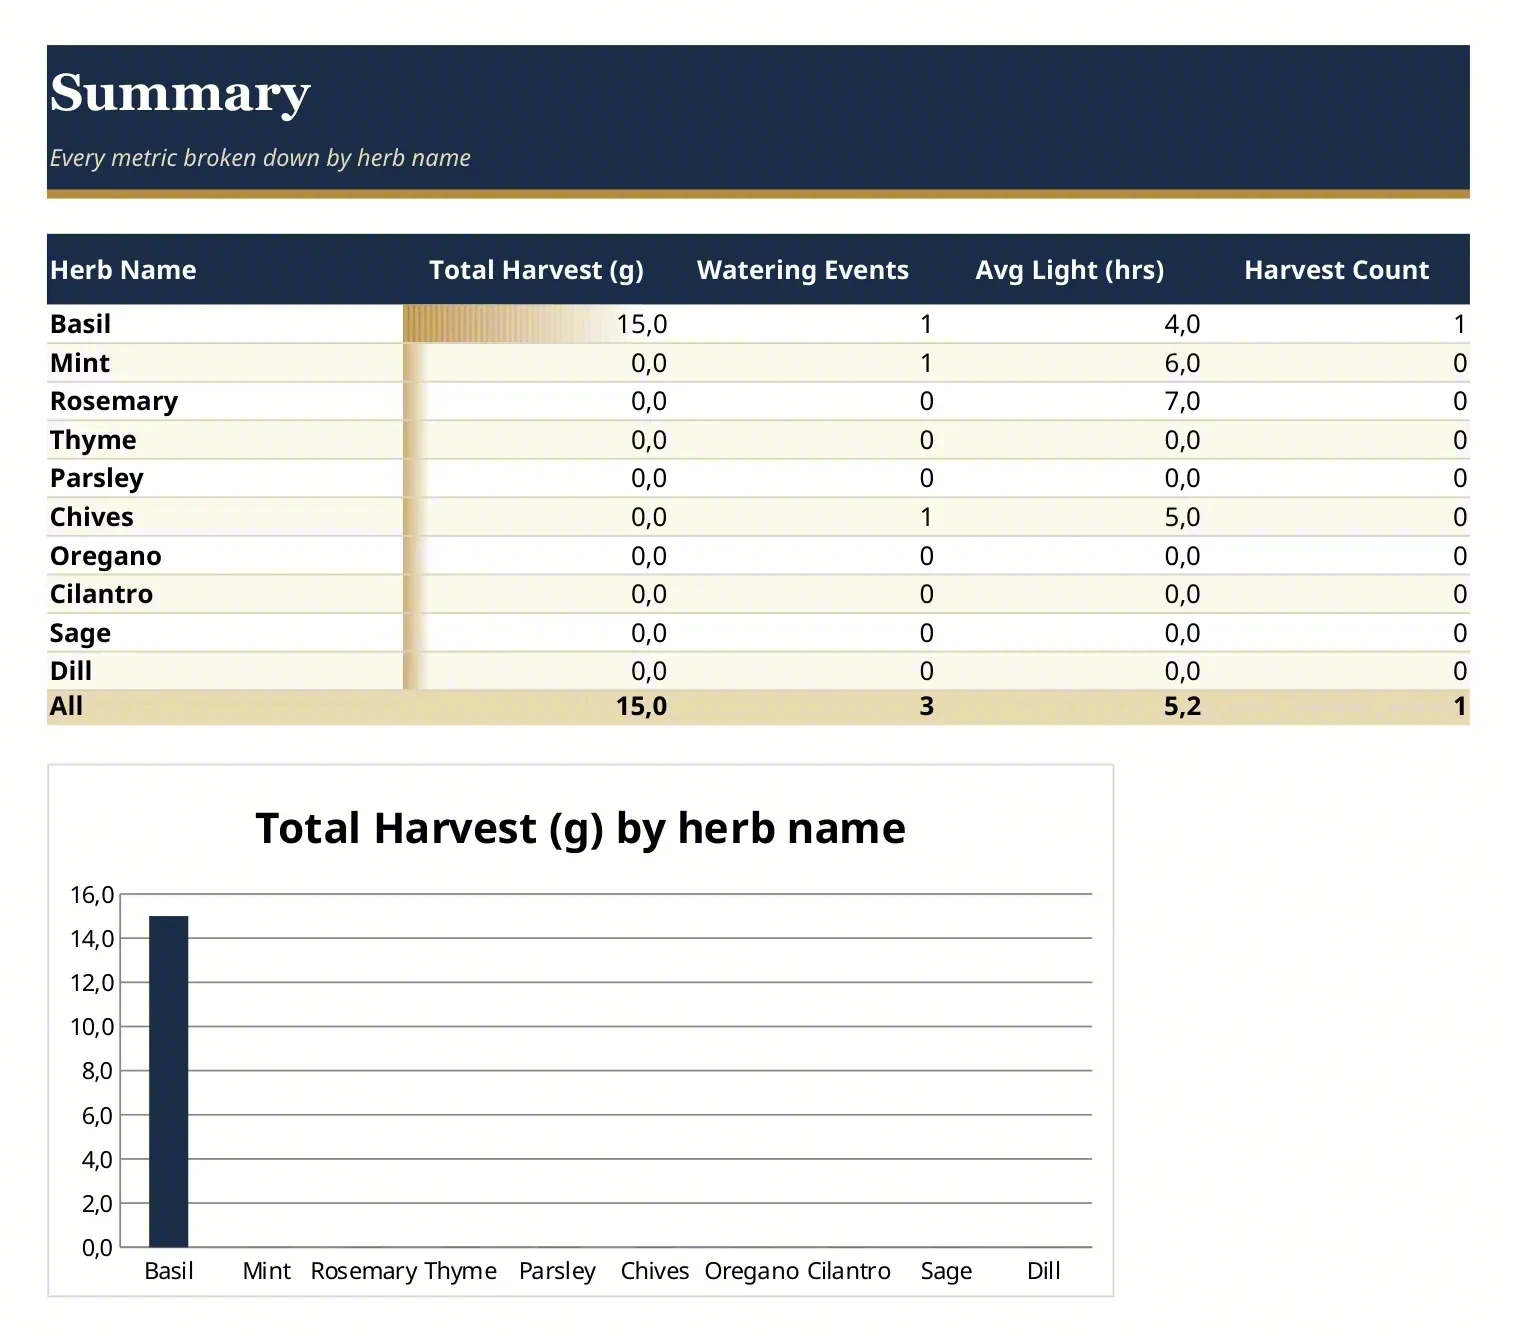
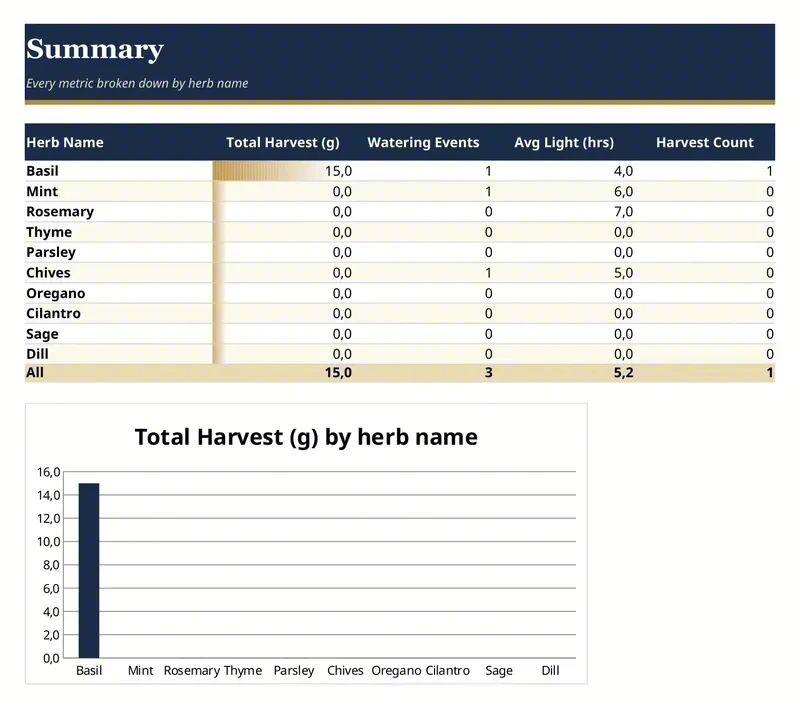 Summary
Two-voice podcast
Two hosts talk through the herb guide. A 35-second excerpt of 2:53.
From idea to edition, measured.
Every stage timed while making the editions on this page.
| Stage | Time | Engine |
|---|---|---|
| 12-page story | 24 s | gemma4 26B |
| 12 consistent illustrations | 9 min 35 s | Qwen-Image 2512 + 4-step Lightning LoRA |
| Storybook narration | 66 s | Kokoro |
| Checks: child safety, character consistency, visual quality | 60 s | Local vision model |
| Print PDF and flipbook | 5 s | Chromium + Paged.js |
| Complete storybook (29 pages) | 16 min | All of the above |
| Practical guide (36 pages, research → layout) | 17 min | gemma4 26B, Chromium + Paged.js |
| Audiobook (20 minutes of listening) | 25 min | Kokoro, with transcription check |
| Two-voice podcast (3 minutes) | 2 min 30 s | Kokoro |
| Interactive calculator | 7 min | gemma4 26B + automated browser tests |
| Notion system | 1 min | gemma4 26B |
| Animated clip from one illustration (3 s) | 50 s | Wan 2.2 5B + 4-step FastWan LoRA |
How we measured
One machine: NVIDIA RTX 4000 Ada 20 GB + 125 GB RAM, October 25, 2026. Times are what the app logged during production, quality checks and retries included. All models run locally; the cloud-call log stayed empty. Your hardware will move these numbers.
- Models
- gemma4 26B (Apache 2.0) for writing; qwen3.6 35B-A3B (Apache 2.0) for outlines and data; Qwen-Image 2512 with the Lightning LoRA (Apache 2.0) for illustration; Kokoro (Apache 2.0) for voice; Wan 2.2 with the FastWan LoRA (Apache 2.0) for video.
- Review
- Every edition waits for human review before release: for children’s books, safety is never auto-approved.
What machine you need
Every sample on this page was made locally with the models below, on one machine: NVIDIA RTX 4000 Ada 20 GB + 125 GB RAM. We have not measured smaller setups yet.
| Products | Models | Memory they use |
|---|---|---|
| Guides, ebooks, planners, checklists, spreadsheets, Notion, calculators | gemma4 26B, qwen3.6 35B-A3B | GPU: ~17 GB for the writing model |
| Picture books and covers | Qwen-Image 2512 + Lightning | 20 GB GPU (tested) |
| Audiobooks, podcasts, narration | Kokoro | Light: also runs without a GPU, slower |
| Video clips | Wan 2.2 5B + FastWan | 20 GB GPU (tested) |
Stages use the GPU one at a time: the card must fit the largest model, not all of them together.
Real editions, not mock-ups.
The first two came out of the app tonight. The others are our first editions, made the hybrid way with local tools and cloud services before the whole pipeline lived in the app.
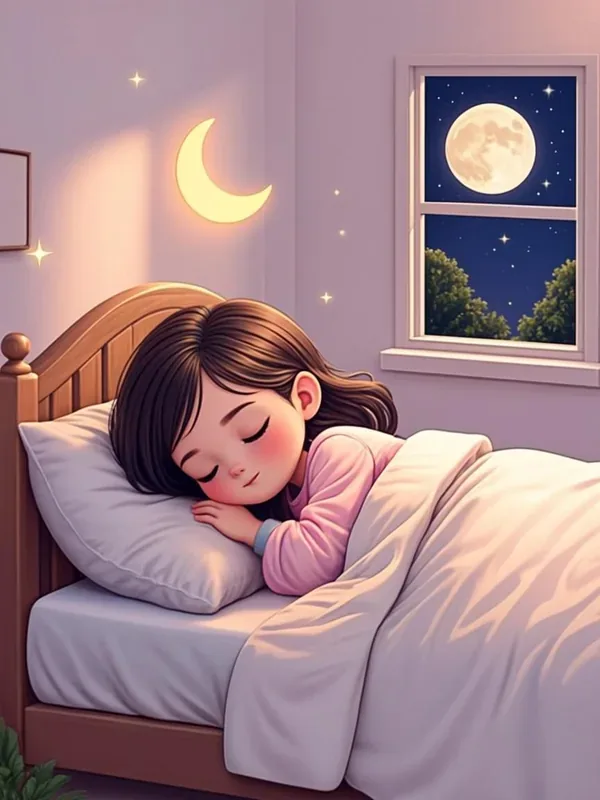
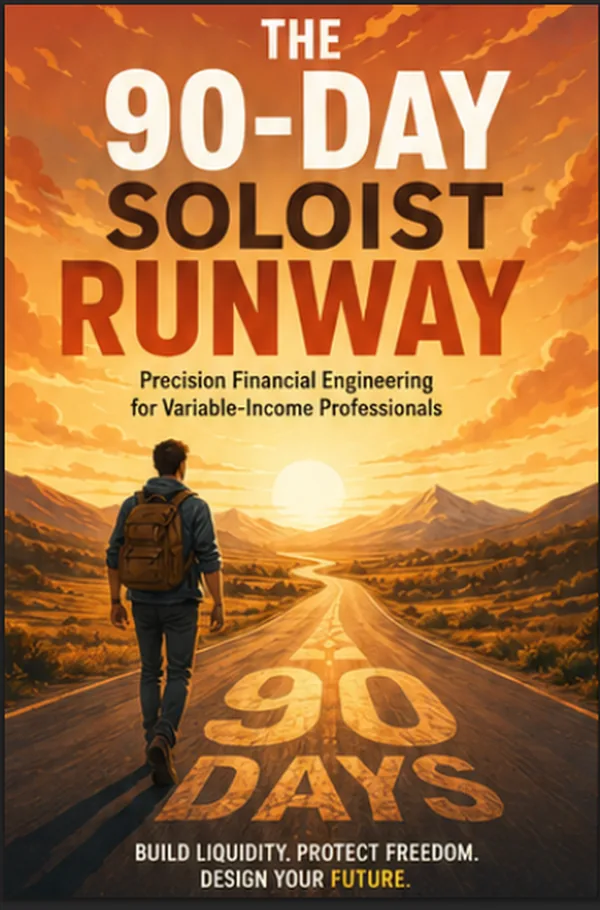
Six steps, one single work.
Each step is one tool in the same app. A human reviews the work before it ships.
- 01
Research
Listens to what people are looking for, before a single word is written.
- 02
Book
Writes and lays out the whole work, from the first page to the last.
- 03
Cover
Designs the cover that makes you stop.
- 04
Illustrations
Draws every page in one consistent style.
- 05
Voice
Reads the work aloud: the audiobook.
- 06
Video
Turns the story into a short animated video.
Velquaria Studio is in the final stage of development: we are finishing the app, the English interface and the installers. Subscribers will hear first.
Text, illustrations, narration and video in these editions are AI-generated and reviewed by a human.
Get the tools before everyone else. Plus a free field guide.
- The guide, right away: which models fit which GPU, the settings that run a 125B model at 60–80 tok/s on 20 GB, the rules that make local coding agents reliable (with our measurements), and a sandbox checklist.
- Early access to Velquaria Forge, then Studio, before the public release.
- One short email when something real ships. Nothing else.
Free. The list runs on Substack (velquaria.substack.com); unsubscribe in one click. Sender: Velquaria, Italy — company details coming soon. Privacy